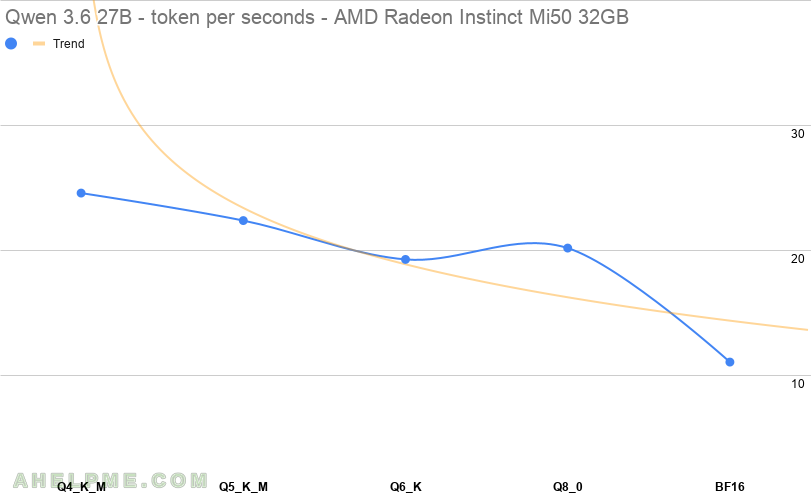
For the LLM model the Alibaba’s Qwen 3.6 27B with different quantization are used to show the difference in token generation per second and memory consumption. Qwen 3.6 27B is relatively small LLM model, but it is extremely good in general AI and software coding. The software engineers could use it not only for sophisticated auto-complete, but also for local agent coding. It is published by the Alibaba giant, and in many cases it can be considered to offload some LLM work locally for free, especially IT. The model is dense with 27B total parameters. Bare in mind, this model is relatively small compared to the bigger one – Qwen 3.5 397B A17B, which is really big LLM with 300 GiB memory for the Q4 at least, but fighting with the very expensive Claude 4.6. The Qwen 3.6 27B is light-weight and dense model, which with enough context data may result in strong agent assistant coding help in the IT. The article is focused only showing the benchmark of the LLM tokens generations per second and there are other papers on the quality of the output for the different quantized version. This model is ideal for even a single AMD Radeon Instinct MI50 32GB card for local inference even with Q8 quantization – perfect for a home use. At present, this cards with AMD Radeon Instinct MI50 32Gb chip are around 550-650$. Building a low cost, but with good inference performance workstation is possible with couple of these cards. Here are the speed and the use can be expected. This article includes a BF16 (brain floating point) of the model using single dual AMD Radeon Instinct MI50 32GB setup cards to load the whole model in the GPU memory. In fact, all tests are made with single and dual setup, except the last one BF16, which could not fit in the memory in a single card. Interesting comparison could be the NVIDIA RTX 3090 24Gb here and the NVIDIA V100, which is also old enterprise grade card (in fact, a direct competitor to AMD Radeon Instinct MI50 32Gb).
In this article prompt processing per second (pp/s) is also included.
The testing bench is:
- Single GPU AMD Radeon Instinct MI50 32GB – 3840 cores
- 32GB RAM HBM2, with 4096 bit bus width.
- Test server – ASUS with single 1950X. Old and cheap CPU, but still good enough for a home lab.
- Link Speed 16GT/s, Width x16
- Testing with LLAMA.CPP – llama-bench
- theoretical memory bandwidth 1.02 TB/s (according to the official documents from AMD)
- the context window is the default 4K of the llama-bench tool. The memory consumption could vary greatly if context window is increased.
- AMD ROCm 7.2.0 version.
- Price: around $550 in ebay.com (Q3 2026).
Here are the results. The first benchmark test is Q4 and is used as a baseline for the diff column below, because Q4 are really popular and they offer a good quality and really small footprint related to the full sized model version.
| N | model | parameters | quantization | memory | pp/s | diff t/s % | tokens/s |
|---|---|---|---|---|---|---|---|
| 1 | Qwen3.6 27B | 26.90 B | Q4_K_M | 15.65 GiB | 176.53 | 0 | 24.554 |
| 2 | Qwen3.6 27B | 26.90 B | Q5_K_M | 18.16 GiB | 117.556 | 8.95 | 22.354 |
| 3 | Qwen3.6 27B | 26.90 B | Q6_K | 20.97 GiB | 154.062 | 13.90 | 19.246 |
| 4 | Qwen3.6 27B | 26.90 B | Q8_0 | 26.62 GiB | 162.666 | -4.71 | 20.154 |
| 5* | Qwen3.6 27B | 26.90 B | BF16 | 50.10 GiB | 75.042 | 45.25 | 11.034 |
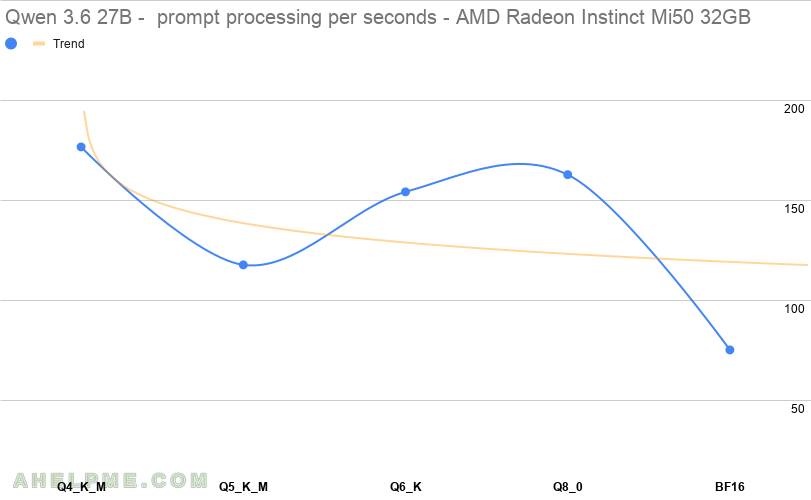
It’s worth noting when the total output tokens increase, the tokens per second does not decrease such with the MoE models. The above table is generated using the least GPUs needed for the test, so Q4_K_M, Q5_K_M, Q6_K and Q8_0 are on a single card setup and the last one, the dual cards for the BF16. From Q4 to BF16 the decrease is 55.06%, which is absolutely usable for local AI inference and agentic work. Around 15 tokens per second is good and usable for daily use for a single user, which is what the GPU inference would offer easily.
1. Qwen 3.6 27B Q4_K_M
Using unsloth Qwen3.6-27B-Q4_K_M.gguf file.
Single AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q4_K_M.gguf -ngl 99
ggml_cuda_init: found 1 ROCm devices (Total VRAM: 32752 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp128 |        147.65 ± 2.99 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp256 |        175.48 ± 1.02 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp512 |        187.63 ± 0.59 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        186.55 ± 0.09 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        185.34 ± 0.08 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           tg128 |         24.57 ± 0.02 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           tg256 |         24.64 ± 0.02 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           tg512 |         24.59 ± 0.01 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         24.58 ± 0.01 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         24.39 ± 0.01 |

build: aac810230 (10908)
Dual AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q4_K_M.gguf -ngl 99
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp128 |        146.23 ± 4.05 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp256 |        174.93 ± 1.03 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp512 |        187.42 ± 0.59 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        244.17 ± 0.21 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        288.16 ± 0.04 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           tg128 |         24.35 ± 0.10 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           tg256 |         24.38 ± 0.04 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           tg512 |         24.40 ± 0.06 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         24.38 ± 0.03 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         24.34 ± 0.01 |

build: aac810230 (10908)
2. Qwen 3.6 27B Q5_K_M
. Using unsloth Qwen3.6-27B-Q5_K_M.gguf file.
Single AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q5_K_M.gguf -ngl 99
ggml_cuda_init: found 1 ROCm devices (Total VRAM: 32752 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           pp128 |        103.78 ± 1.44 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           pp256 |        117.08 ± 0.41 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           pp512 |        122.79 ± 0.26 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        122.31 ± 0.02 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        121.82 ± 0.04 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           tg128 |         22.43 ± 0.02 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           tg256 |         22.39 ± 0.01 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           tg512 |         22.35 ± 0.01 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         22.34 ± 0.01 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         22.26 ± 0.00 |

build: aac810230 (10908)
Dual AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q5_K_M.gguf -ngl 99
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           pp128 |        102.94 ± 2.06 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           pp256 |        116.88 ± 0.47 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           pp512 |        122.87 ± 0.26 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        160.54 ± 0.09 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        189.76 ± 0.05 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           tg128 |         22.39 ± 0.03 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           tg256 |         22.41 ± 0.08 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |           tg512 |         22.41 ± 0.07 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         22.38 ± 0.03 |
| qwen35 27B Q5_K - Medium       |  18.16 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         22.33 ± 0.01 |

build: aac810230 (10908)
3. Qwen 3.6 27B Q6_K
Using unsloth Qwen3.6-27B-Q6_K.gguf file.
Single AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q6_K.gguf -ngl 99
ggml_cuda_init: found 1 ROCm devices (Total VRAM: 32752 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           pp128 |        134.39 ± 2.18 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           pp256 |        154.04 ± 0.80 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           pp512 |        161.39 ± 0.44 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        160.63 ± 0.06 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        159.86 ± 0.06 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           tg128 |         19.34 ± 0.01 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           tg256 |         19.29 ± 0.01 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           tg512 |         19.24 ± 0.01 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         19.22 ± 0.00 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         19.14 ± 0.01 |

build: aac810230 (10908)
Dual AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q6_K.gguf -ngl 99
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           pp128 |        133.19 ± 3.39 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           pp256 |        153.95 ± 0.83 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           pp512 |        161.36 ± 0.43 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        210.60 ± 0.12 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        248.78 ± 0.11 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           tg128 |         19.56 ± 0.01 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           tg256 |         19.54 ± 0.04 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |           tg512 |         19.57 ± 0.02 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         19.54 ± 0.03 |
| qwen35 27B Q6_K                |  20.97 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         19.49 ± 0.01 |

build: aac810230 (10908)
4. Qwen 3.6 27B Q8_0
Using unsloth Qwen3.6-27B-Q8_0.gguf file.
Single AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q8_0.gguf -ngl 99
ggml_cuda_init: found 1 ROCm devices (Total VRAM: 32752 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           pp128 |        141.78 ± 2.63 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           pp256 |        161.64 ± 0.39 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           pp512 |        169.72 ± 0.58 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        170.24 ± 0.09 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        169.95 ± 0.05 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           tg128 |         20.16 ± 0.01 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           tg256 |         20.21 ± 0.01 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           tg512 |         20.16 ± 0.00 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         20.14 ± 0.00 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         20.10 ± 0.00 |

build: aac810230 (10908)
Dual AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-Q8_0.gguf -ngl 99
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           pp128 |        140.38 ± 3.57 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           pp256 |        161.78 ± 0.81 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           pp512 |        169.48 ± 0.50 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        224.07 ± 0.06 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        265.44 ± 0.14 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           tg128 |         19.59 ± 0.06 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           tg256 |         19.63 ± 0.06 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |           tg512 |         19.63 ± 0.04 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         19.62 ± 0.03 |
| qwen35 27B Q8_0                |  26.62 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         19.58 ± 0.00 |

build: aac810230 (10908)
5. Qwen 3.6 27B BF16
Using unsloth Qwen3.6-27B-BF16-00001-of-00002.gguf and Qwen3.6-27B-BF16-00001-of-00002.gguf files.
Dual AMD Radeon Instinct MI50 32GB:
llama-bench -t 16 -p 128,256,512,1024,2048 -n 128,256,512,1024,2048 -m /root/models/unsloth/Qwen3.6-27B-BF16-00001-of-00002.gguf -ngl 99
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |           pp128 |         55.16 ± 0.64 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |           pp256 |         63.75 ± 0.20 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |           pp512 |         66.29 ± 0.07 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |          pp1024 |         86.95 ± 0.06 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        103.06 ± 0.06 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |           tg128 |         11.03 ± 0.01 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |           tg256 |         11.04 ± 0.02 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |           tg512 |         11.05 ± 0.02 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |          tg1024 |         11.03 ± 0.00 |
| qwen35 27B BF16                |  50.10 GiB |    26.90 B | ROCm       |  99 |          tg2048 |         11.02 ± 0.00 |

build: aac810230 (10908)
Bear in mind that there is an additional latency because of the data transfer between the two cards using the PCI-E. Running BF16 is only possible with two cards with 32Gb RAM.
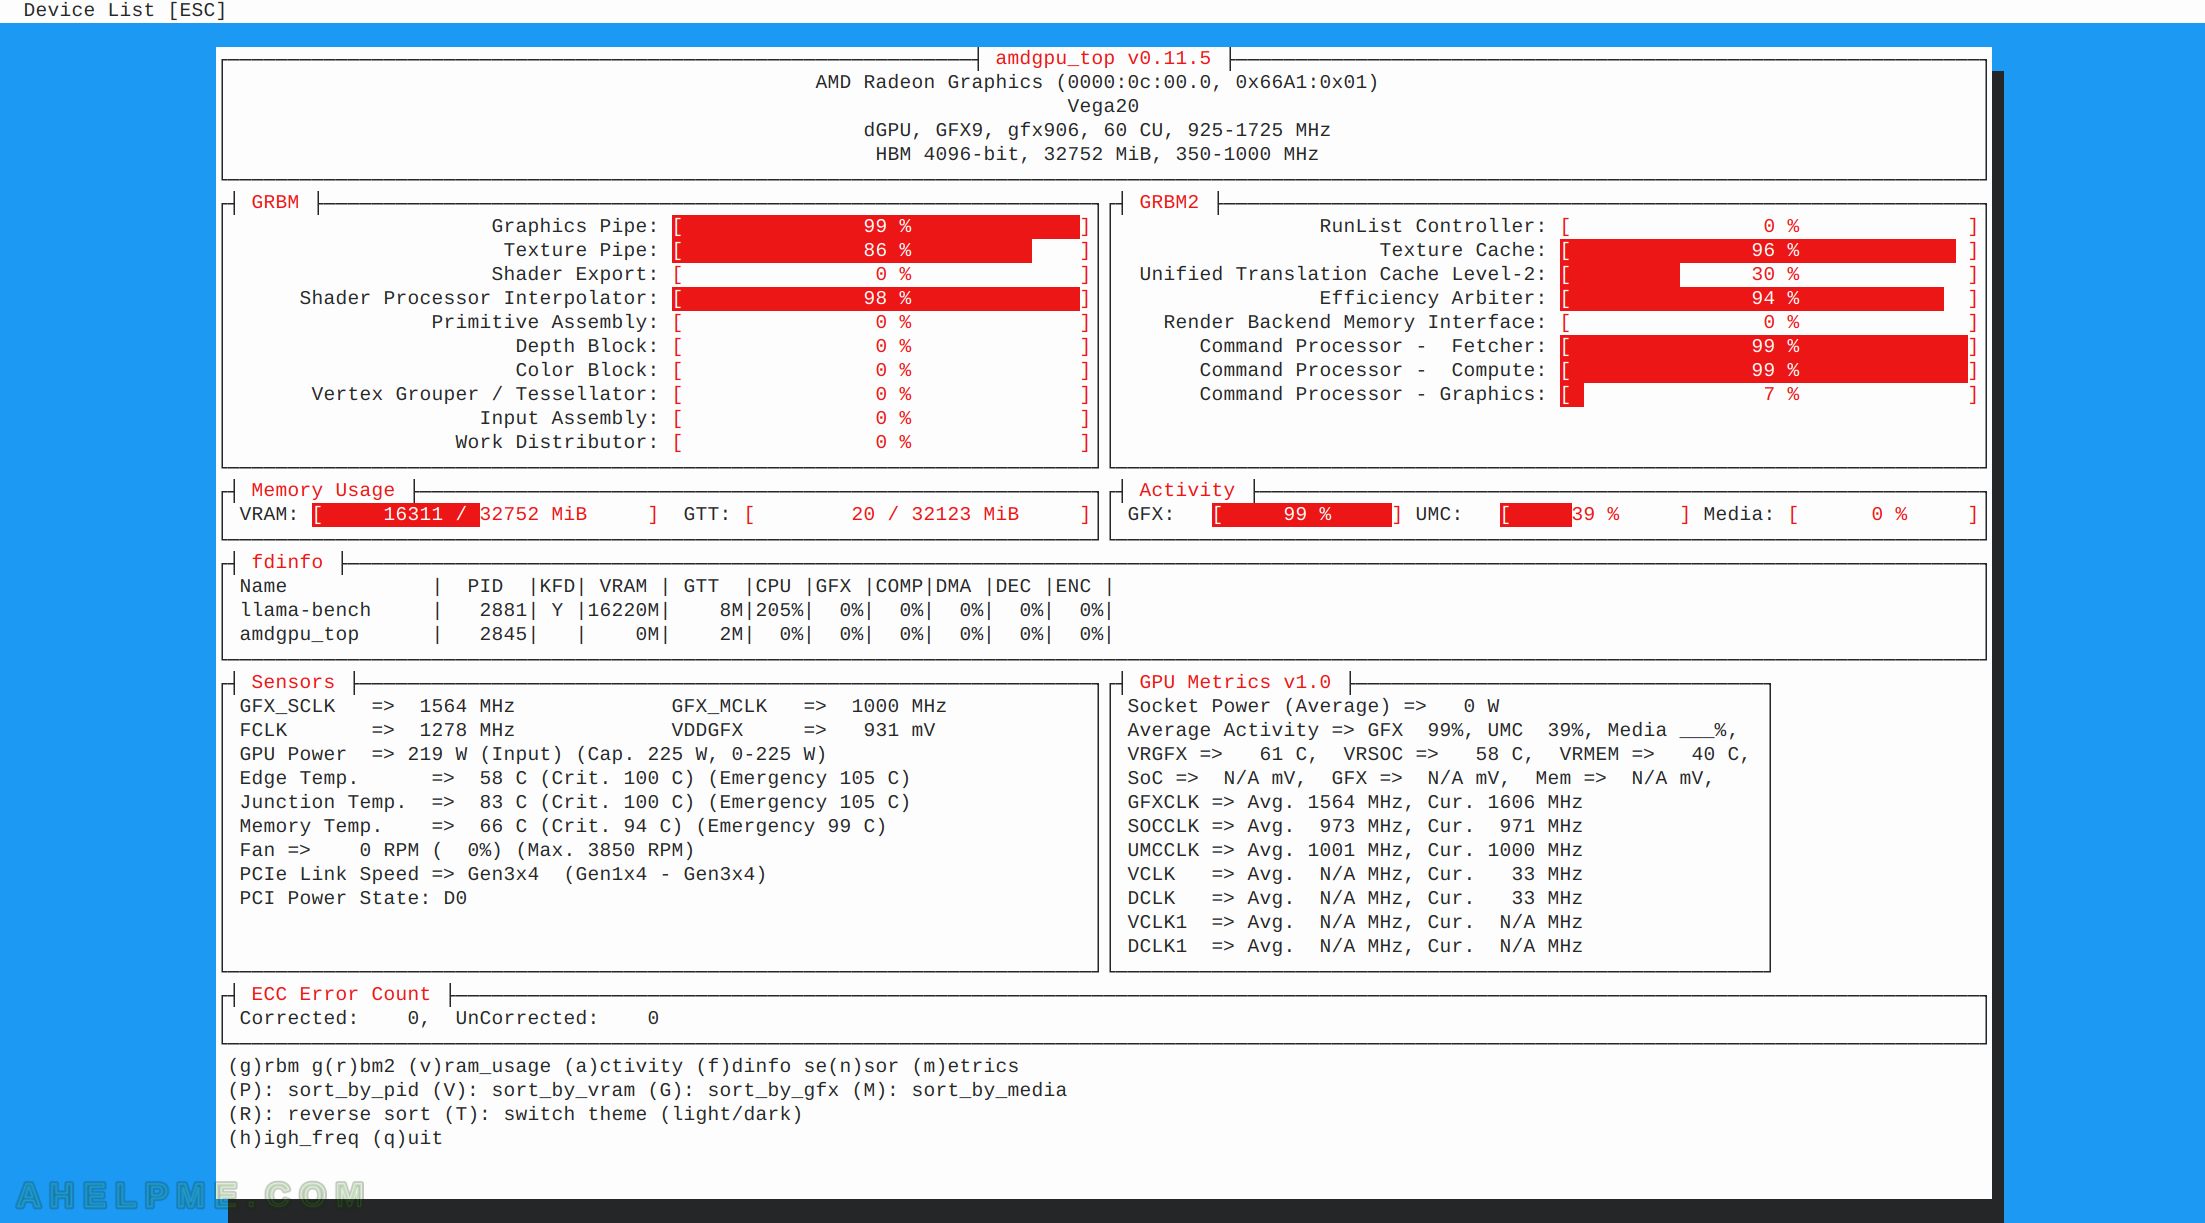
rocm-smi when benchmarking the prompt processing and the second is for token generation:
rocm-smi

============================================ ROCm System Management Interface ============================================
====================================================== Concise Info ======================================================
Device  Node  IDs              Temp    Power     Partitions          SCLK     MCLK     Fan     Perf  PwrCap  VRAM%  GPU%
              (DID,     GUID)  (Edge)  (Socket)  (Mem, Compute, ID)
==========================================================================================================================
0       2     0x66a1,   46520  56.0°C  227.0W    N/A, N/A, 0         1725Mhz  1000Mhz  23.92%  auto  225.0W  26%    100%
1       3     0x66a1,   17656  55.0°C  196.0W    N/A, N/A, 0         1725Mhz  800Mhz   23.53%  auto  225.0W  29%    100%
==========================================================================================================================
================================================== End of ROCm SMI Log ==================================================

rocm-smi

============================================ ROCm System Management Interface ============================================
====================================================== Concise Info ======================================================
Device  Node  IDs              Temp    Power     Partitions          SCLK     MCLK     Fan     Perf  PwrCap  VRAM%  GPU%
              (DID,     GUID)  (Edge)  (Socket)  (Mem, Compute, ID)
==========================================================================================================================
0       2     0x66a1,   46520  45.0°C  239.0W    N/A, N/A, 0         925Mhz   350Mhz   16.08%  auto  225.0W  25%    0%
1       3     0x66a1,   17656  48.0°C  248.0W    N/A, N/A, 0         1485Mhz  1000Mhz  17.65%  auto  225.0W  28%    68%
==========================================================================================================================
================================================== End of ROCm SMI Log ==================================================
Before all tests the cleaning cache commands were executed:
echo 0 > /proc/sys/kernel/numa_balancing
echo 3 > /proc/sys/vm/drop_caches
Bonus – big prompt processing
Benchmark with only prompt processing from 128 to 131072 tokens with dual cards and Qwen3.6 27B Q4_K_M.
llama-bench -t 16 -p 128,256,512,1024,2048,4096,8192,16384,32768,65536,131072 -n 0  -m /root/models/unsloth/Qwen3.6-27B-Q4_K_M.gguf -ngl 99
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
| model                          |       size |     params | backend    | ngl |            test |                  t/s |
| ------------------------------ | ---------: | ---------: | ---------- | --: | --------------: | -------------------: |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp128 |        146.04 ± 4.75 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp256 |        174.97 ± 1.19 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |           pp512 |        187.66 ± 0.53 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp1024 |        244.25 ± 0.30 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp2048 |        288.52 ± 0.31 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp4096 |        315.17 ± 0.24 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |          pp8192 |        326.56 ± 0.18 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |         pp16384 |        324.23 ± 0.10 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |         pp32768 |        308.13 ± 0.15 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |         pp65536 |        275.44 ± 0.11 |
| qwen35 27B Q4_K - Medium       |  15.65 GiB |    26.90 B | ROCm       |  99 |        pp131072 |        225.03 ± 0.11 |

build: aac810230 (10908)
For more LLM performance benchmarks with llama-bench check out – here.